Every week brings another breathless demo: a model that writes code, drafts a contract, plans a campaign, plays the role of a tireless salesperson. Every week also brings another quiet postmortem inside a company that bought the demo and discovered, six months later, that nothing about its cost structure, its cycle time, or the quality of its decisions had actually changed. That gap — between what a model can do on a stage and what a firm can execute inside its own operations — is where the next cycle of winners is being decided. Not in the benchmark charts. In the plumbing.
The pattern repeats because the hype cycle measures the wrong thing. It measures capability. It celebrates parameter counts, leaderboard percentages, and the novelty of a generated artifact. Businesses, meanwhile, run on predictability, cost per transaction, cycle time, and the reliability of a decision repeated ten thousand times a day. A model that produces a beautiful one-off output is not the same asset as a system that makes the same mundane judgment a million times, with measured variance and a known failure mode. The first is a demo. The second is a business.
Capability Is Not the Bottleneck — Execution Is
There is a specific intellectual error that keeps otherwise sharp operators stuck in the hype cycle: the belief that market disruption requires something like general intelligence. If you assume you need a system that reasons about anything, you spend your roadmap waiting. You pilot, you evaluate vendors, you run a proof of concept in a sandbox, and you postpone the real work — which is rewiring how decisions move through your company.
Structural business reality is far less glamorous. Market-defining transformation only requires narrow statistical prediction: systems that reliably perform discrete, high-frequency operational choices that were previously bound by a human decision bottleneck. Which invoice is likely fraudulent. Which lead is likely to convert this week. Which route will miss the delivery window. Which customer is about to churn. None of these require consciousness. All of them require clean data, a feedback loop, and the nerve to let a model act.
Once prediction is digitized, organizational economics change at the root. Digitized operational data can be replicated, transmitted, and executed at near-zero marginal cost. It can be connected across complementary services. It can be continuously optimized through automated telemetry rather than quarterly management review. The asset compounds while you sleep, which is precisely the property that human decision-making lacks.
The Economics of Cheap Prediction
The cleanest way to think about artificial intelligence as a founder is not as a product category but as a price change. In Power and Prediction, economists Ajay Agrawal, Joshua Gans, and Avi Goldfarb make the argument that the fundamental economic effect of machine learning is a drastic reduction in the cost of prediction. Prediction is the input that converts raw activity data into decisions under uncertainty — and when the cost of a foundational input collapses, its usage expands into places that were previously cost-prohibitive.
That last part matters more than it sounds. Cheap prediction does not simply make existing forecasts cheaper. It makes entirely new categories of decisions economically viable. Historically, managerial decision-making under uncertainty relied on slow, intuitive human heuristics. Those heuristics introduce operational variability, they do not scale past the manager’s attention span, and they carry a hidden administrative overhead in the form of meetings, escalations, and exceptions. Industrializing prediction turns decision-making from a judgment call into a software input.
Consider what that does to a pricing team. In the old model, a pricing analyst reviews a spreadsheet weekly and adjusts a handful of price points. In the prediction-cheap model, price is a live output that responds to inventory, demand elasticity, competitor signals, and customer lifetime value — for every SKU, every hour. Nobody hired more analysts. The input just got cheap enough that the decision no longer needed to be batched.
Why AI-First Language Often Produces Nothing
Enterprise leaders love the vocabulary of the paradigm shift. Satya Nadella has described AI as the runtime that will shape everything a company does; Sundar Pichai pushed an AI-first posture years before it was fashionable. Both statements are correct, and both are routinely misread by teams that treat AI as an additive feature rather than an architectural foundation.
Adding a chatbot to a legacy portal is not an AI strategy. It is a wrapper. The execution path underneath — who approves, who decides, where the data is stored, how the result is measured — remains untouched. Three structural failure modes show up again and again when organizations take this shortcut:
- The legacy layering trap. Machine learning models are draped over siloed, non-standardized databases. Because each functional system holds a fragment of the truth, the algorithm never sees the holistic operational picture required for continuous learning, and its accuracy plateaus at whatever the silo allows.
- The human execution bottleneck. Manual approval steps survive in the highest-volume operational paths. Every retained human checkpoint preserves managerial complexity cost and hard-caps operational scale, no matter how good the model is.
- The static architecture deficit. Monolithic codebases without standardized interfaces cannot integrate with cloud services, third-party developers, or even the company’s own internal tools. Integration cost eats the return before the model ever ships.
The uncomfortable implication is that most AI failure is not an AI problem. It is an architecture problem and an operating-model problem wearing an AI costume.
Business Model and Operating Model Have to Move Together
In Competing in the Age of AI, Marco Iansiti and Karim Lakhani argue that durable firm performance depends on alignment between a company’s business model and its operating model. Natively deployed AI alters both sides of that equation at once, which is exactly why half-measures underperform so badly: you end up with a new promise and an old delivery machine.
The business model splits into two distinct questions that founders often conflate. Value creation is the customer promise: what specific problem do you solve, and how well? AI-native value creation looks different from feature-based value creation because it is dynamic — personalized to the individual, continuously available, responsive to context, and capable of solving the long tail of problems a static product ignores.
Value capture is the monetization mechanism, and here the divergence is sharper still. A traditional firm captures value through a static margin per unit: price minus cost, multiplied by volume. An AI-native platform separates creation from capture and monetizes engagement across an interconnected ecosystem. The difference in growth behavior is not incremental; it is structural.
- Traditional structure: linear pricing per unit, margin equals price minus cost, growth limited by assets, headcount, and physical capacity.
- Platform structure: multisided monetization driven by number of participants, depth of engagement, and monetization rate per engagement across connected services.
- Primary value driver: algorithmic optimization, near-zero marginal distribution cost, and network effects rather than owned assets.
Written as an equation, platform value capture scales as participants multiplied by engagement depth multiplied by monetization rate. Each factor compounds the others. That is why a platform with a mediocre model but a healthy network beats a platform with an excellent model and no network, and it is why founders who optimize only for model quality tend to lose to founders who optimize for the loop.
Scale, Scope, and Learning: The Operating Triad
An operating model is the machinery that actually delivers whatever the business model promises, and it moves along three vectors. Scale is the ability to serve a huge population at near-zero marginal cost — software-driven models expand capacity with minimal incremental effort, while traditional models accumulate coordination friction and management overhead as volume grows. Scope is the ability to add adjacent products by linking complementary activities through modular architecture, so the second product costs far less than the first. Learning is the ability to improve automatically from every transaction through statistical feedback and controlled experimentation.
Learning is the vector most companies fake. They collect dashboards. They hold retrospectives. They do not run experiments at a rate that produces statistically defensible knowledge, and so their operating model accumulates opinions rather than compounding intelligence. A firm that ships two hundred properly randomized tests a year knows something its competitor cannot buy, copy, or hire its way into.
The growth dynamics follow directly. Traditional operating models hit diminishing returns and rising organizational complexity as they scale; human coordination overhead bends the cost curve upward and caps growth. AI-native operating models remove human execution from the critical path, so operational performance improves while marginal cost approaches zero as volume and data grow. That is an unbounded curve versus a bounded one, and no amount of hiring fixes the bounded one.
Architectural Inertia and the Shadow of Conway’s Law
Conway’s Law observes that a system’s architecture mirrors the communication structure of the teams that built it. The implication for AI programs is brutal: if your company is organized in functional silos, your data will be siloed, your models will be siloed, and every attempt at cross-functional automation will require a meeting that costs more than the automation saves.
Clayton Christensen’s work on disruptive innovation, and Rebecca Henderson and Kim Clark’s research on architectural innovation, explain why incumbents struggle here even when they see the threat clearly. Established organizations build entrenched routines aligned to functional boundaries. The result is architectural inertia — a structural inability to reconfigure the linkages between components, even when every individual component improves.
This is the difference between component innovation and architectural innovation, and it decides who wins. Dropping an analytics tool into the marketing department is component innovation. Re-architecting the linkages that connect data ingestion, predictive models, and automated execution across the entire enterprise is architectural innovation. The first produces a pilot that dies quietly. The second produces a company that gets cheaper to run as it gets bigger.
Inside the AI Factory
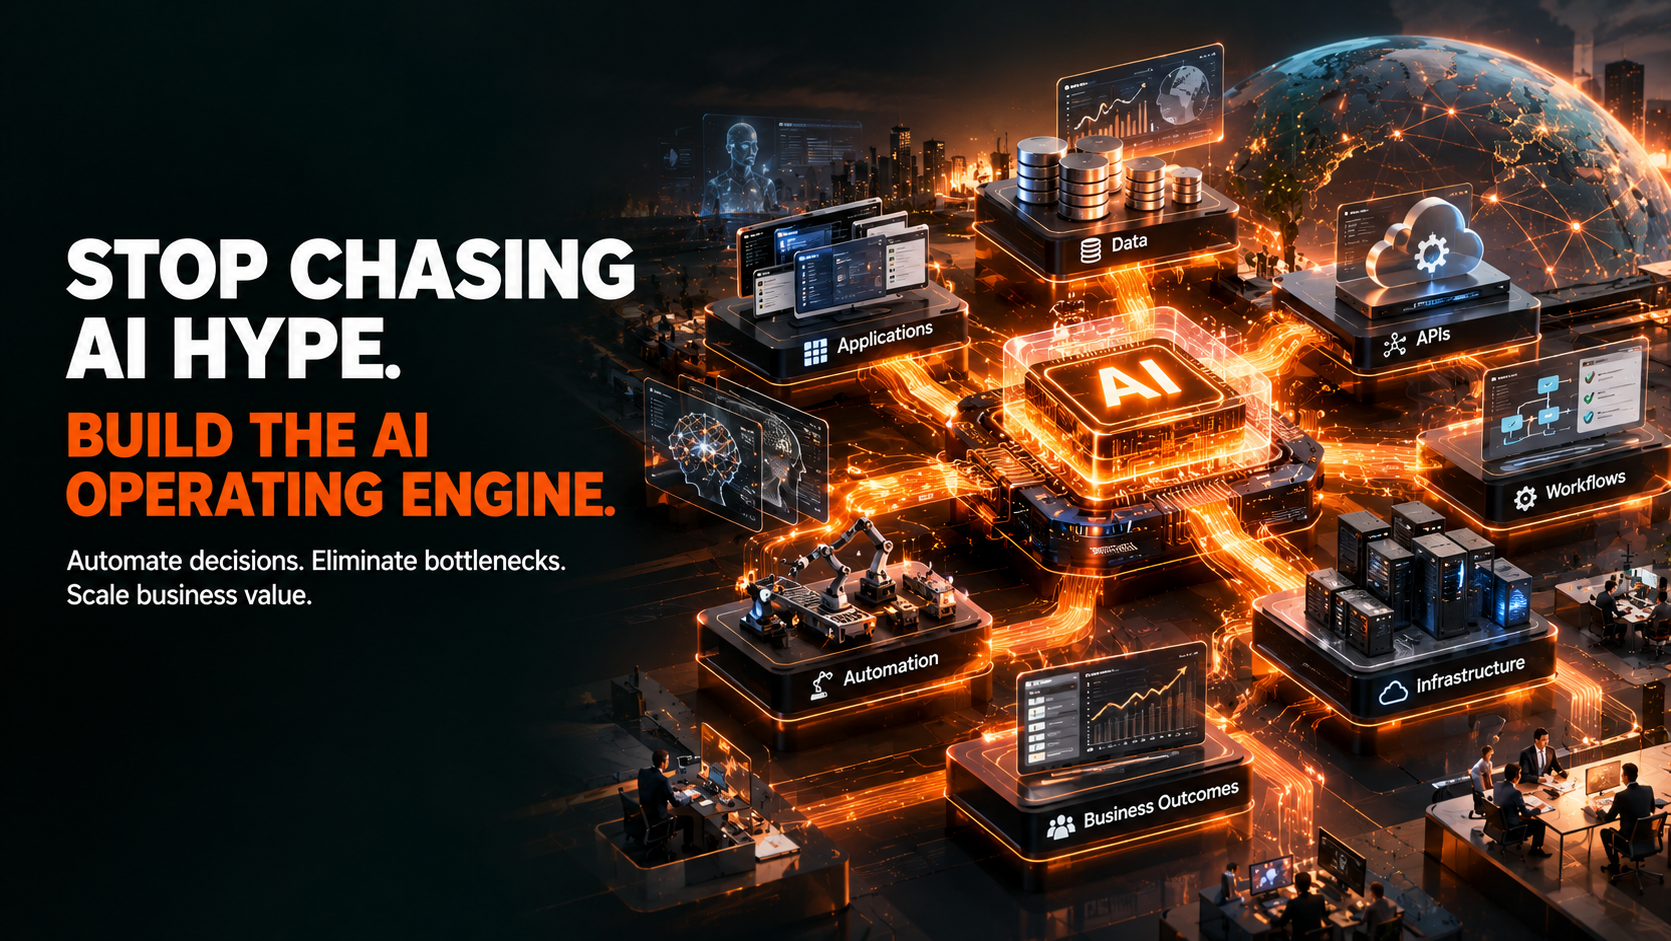
The concrete artifact of an AI-native operating model is what the literature calls an AI factory: the scalable decision engine that industrializes data collection, model training, prediction generation, and software deployment. It has four production lines, and weakness in any one of them caps the whole.
- Data pipeline. Gathering, cleaning, normalizing, integrating, and safeguarding operational data so that it is machine-readable and trustworthy at the point of decision.
- Algorithmic architecture. Supervised learning for labeled mapping problems, unsupervised learning for structure and anomaly discovery, reinforcement learning and multi-armed bandits for sequential decisions where exploration has a price.
- Experimentation platform. Formalized hypotheses and randomized controlled tests that move the organization from correlation to causal verification.
- Modular software infrastructure. Publish-subscribe data access, microservices, and standardized interfaces so the whole assembly can be recombined and extended.
Datafication is the first real discipline. Ming Zeng’s framing is useful: datafication is the systematic conversion of ongoing operational activity into structured, machine-readable datasets. Nest datafied home climate control by capturing ambient temperature and occupancy patterns to automate HVAC efficiency. Pitney Bowes, a postal equipment manufacturer, datafied physical mailing addresses into location intelligence products that now power enterprise analytics and fraud detection. In both cases the asset was not the algorithm. The asset was the newly created dataset and the operational loop that keeps refreshing it.
The pipeline itself has five unglamorous steps that determine whether anything downstream works: systematic gathering of interaction telemetry across interfaces, devices, and transactional systems; cleaning to filter sensor noise and reconcile anomalies; normalization of structures, units, and definitions across domains; integration into an accessible lake or publish-subscribe layer; and safeguarding through identity controls, encryption, and governance. Teams that skip normalization pay for it forever, because two departments measuring the same thing differently will produce a model that is confidently wrong in both directions.
Prediction Is Cheaper Than Proof, So Build the Test Rig
Statistical models surface correlations. Operations demand causality. A pricing model can learn that discounting correlates with volume without the relationship being causal, and acting on that belief can quietly destroy margin for a year before anyone notices. High-performing AI factories therefore treat experimentation as infrastructure rather than as a growth tactic: every predictive model is subjected to continuous randomized trials before and after it is allowed to touch the critical path.
The Harvard Laboratory for Innovation Science case is a good illustration of what a properly assembled factory can do in weeks rather than years. Mapping the three-dimensional boundary of a lung tumor on CT scans traditionally required roughly eight minutes of manual oncologist labor per scan. LISH ran crowdsourced algorithm contests through Topcoder across 461 patient cases and about 77,000 CT image slices. Within ten weeks, the resulting deep learning models mapped tumor boundaries in 15 to 120 seconds per scan, matching the accuracy of Harvard-trained radiation oncologists and outperforming existing commercial clinical software.
Note what made that possible: a standardized pipeline, a defined evaluation metric, a large labeled dataset, and a competition harness that turned many parallel attempts into one comparable result. The win came from the factory, not from a single genius architecture.
Modularity Is a Governance Decision
An AI factory cannot scale if the software stays tightly coupled. Microservice architectures connected by standardized interfaces let product teams build, test, and release independently, which is the only way iteration speed survives contact with organizational growth. The canonical blueprint is still Jeff Bezos’s 2002 API mandate at Amazon: all teams expose data and functionality through service interfaces; teams communicate only through those interfaces; no direct linking, no direct reads of another team’s data store, no back doors; and every interface must be designed from the ground up to be externalizable.
That last clause is the strategic one. Interfaces designed to be external became the foundation of Amazon Web Services, an entirely new business built on internal plumbing that had been made modular on purpose. Founders who treat API design as a technical chore rather than a strategic choice are choosing, often unknowingly, a lower ceiling.
Take Humans Off the Critical Path
The defining operational transition of winning AI ventures is deliberate: remove manual human labor from the real-time execution path of product delivery, and redeploy that talent into design, integration, and oversight. In the traditional path, a customer request passes through manual review and human decision before delivery. Throughput is capped by hiring budgets, training cycles, and human speed. In the AI-native path, the request hits an automated pipeline, a prediction engine evaluates it, and execution happens instantly — with humans positioned above the path as system designers, integrators, and guardians rather than inside it as toll booths.
This is not a philosophical position about automation. It is arithmetic. If a human must touch every transaction, your marginal cost per transaction is a labor cost, and your growth rate is a recruiting rate. Ant Financial’s MYbank made the arithmetic visible with its three-one-zero lending model: three minutes to apply on a mobile device, one second for automated credit approval, zero human intervention. Evaluating real-time behavioral data across Alibaba’s ecosystem, the system weighs thousands of risk variables per application and processes a loan at an operational cost of roughly two RMB per transaction, against a figure in the thousands at traditional banks. An organization of a few hundred employees serves millions of small businesses.
Ocado shows the same principle in physical operations. Its automated fulfillment centers span an area comparable to eleven soccer fields, with tens of miles of conveyors and thousands of coordinated picking bots. Predictive algorithms route the fleet in real time, forecast supply constraints days ahead, and direct robots to assemble fifty-item grocery orders in minutes with a 98.5 percent on-time rate. Peloton shows it in content: a studio instructor at a traditional cycling class teaches thirty riders, while a single streamed class reaches twenty thousand simultaneous participants, producing recurring subscription revenue with retention near 95 percent. Different industries, identical move — find the human bottleneck, then restructure so that one human serves thousands instead of dozens.
Crossing the Chasm Means Selling Utility, Not Novelty
Geoffrey Moore’s adoption model still describes the failure mode accurately. Technology ventures stall in the chasm when they delight visionaries with generative novelty and then discover that pragmatist buyers want reliability, integration, and provable operational improvement. Visionaries buy possibility. Pragmatists buy reduced cost per outcome.
This is why hype-driven startups sell model capability while cycle-winning ventures sell domain-specific AI factories that automate operational touchpoints, lower unit economics, and eliminate execution bottlenecks. The pitch that closes a pragmatist is not “our model is smarter.” It is “your claims team’s cycle time drops from nine days to four hours, and here is the audit trail.”
The Cold Start Problem and the Data Flywheel
Every AI-native venture runs into the same wall early: the model is not good yet because there is no data, and there is no data because the product is not good yet. Escaping this requires engineering a self-reinforcing loop rather than waiting for one to emerge.
- Capture baseline telemetry from a narrow, high-frequency workflow where you can instrument everything.
- Train a specialized model on curated domain data rather than a general-purpose one on everything.
- Ship a visibly better experience so the product earns repeat usage on merit, not novelty.
- Increase interaction volume deliberately, through workflow placement rather than marketing spend.
- Compound the data asset until the accumulated dataset becomes a barrier a new entrant cannot buy.
Multisided scope follows the same logic. Tencent’s WeChat evolved from a desktop messaging service into a mobile ecosystem by opening interfaces to third-party developers, folding payments, utility billing, appointments, and commerce into one surface, which lowered acquisition cost while raising lifetime value. Amazon’s Alexa turned cheap microphone hardware into an ecosystem hub by opening a skills platform to tens of thousands of external developers. In both cases, scope expansion was close to free because the architecture had been built to be extended.
What Enterprise Buyers Actually Evaluate
For B2B ventures, product-market fit in the AI era is inseparable from stack fit. Enterprise information architects evaluate integration along four practical axes, and failing any one of them usually kills the deal regardless of model quality.
- API modularity: can the capability slot into existing CRM, ERP, and data lake systems without custom rewrite work?
- Real-time telemetry: does every interaction flow back to update the central model, or does learning stop at the demo boundary?
- Automated orchestration: do algorithmic outputs execute inside the tools employees and customers already use, or do they wait in another dashboard?
- Governance: are permissions, data isolation, and compliance auditing strong enough for a regulated buyer’s review board?
Platforms built for this kind of integration — the ones that digitize manual touchpoints, unify fragmented data streams, and let workflow decisions run without adding administrative overhead — are structurally advantaged, because every new customer makes the operating model stronger rather than heavier.
A Diagnostic for Leadership Teams
Before committing capital to an AI roadmap, score the organization honestly on four dimensions. The scale runs from zero to three, where zero means legacy posture and three means genuinely next-cycle ready.
- Data infrastructure: fragmented, siloed, non-standard formats at the low end; a unified publish-subscribe platform with automated cleaning, normalization, and a secure internal interface registry at the high end.
- Algorithmic integration: isolated ad hoc projects and dashboards viewed manually at the low end; predictive models executing real-time pricing, routing, or approval decisions on the critical path at the high end.
- Critical path automation: manual review required for daily operational choices at the low end; humans exclusively designing, integrating, and guarding systems at the high end.
- Architectural flexibility: monolithic code and tight coupling mirroring functional silos at the low end; modular services, autonomous teams, and externalizable interfaces at the high end.
Most companies score high on ambition and low on the third dimension, which is the one that determines whether the economics ever change. A useful discipline: pick a single high-volume decision, measure the fully loaded cost of the human path today, and commit to moving that decision onto an automated path within a quarter. One moved decision teaches the organization more than a year of strategy decks.
Governance Is a Scaling Requirement, Not a Compliance Tax
Unbounded scale, scope, and learning create systemic risk in direct proportion. Three practices are non-negotiable once a model touches real customers and real money. Audit training data continuously so predictions do not launder historical human bias into automated decisions at machine speed. Enforce centralized data governance, zero-trust access, and interface throttling so corporate data cannot be extracted quietly. And establish explicit oversight boundaries with monitoring on automated outcomes, so that reliability, regulatory posture, and accountability survive the removal of the human checkpoint.
Founders who treat these as paperwork discover that governance is actually a sales asset. The first enterprise deal that stalls in a security review is a reminder that the fastest path to a large contract often runs through controls you built before you needed them.
What a Real Reallocation Looks Like
Microsoft’s transformation remains the most legible reference model because it was expensive, structural, and public. The company committed several billion dollars annually in cloud capital expenditure, re-architected Azure to support Linux and open-source ecosystems that it had previously treated as competitors, and restructured its organization around new leadership responsibilities spanning cloud, AI, and core services engineering. Conviction backed by patience, with the operating model rebuilt before the marketing changed.
The lesson is not that every founder needs a data center. It is that the reallocation is the strategy. Budget moves from one line to another, decision rights move from one team to another, and the critical path is genuinely rerouted. Announcements without reallocation are the signature of the hype cycle; reallocation without announcements is the signature of the companies quietly taking share.
Where the Next Cycle Is Actually Being Won
The founders who will own the next cycle are, right now, doing something that produces no press coverage. They are normalizing data schemas. They are arguing about interface contracts. They are instrumenting a workflow nobody outside the company has heard of, measuring the cost of the human path, and then deleting that path. They are building decision engines that get measurably better every week because the feedback loop is wired and the experiments are honest.
Meanwhile, the noisiest companies in the market are shipping wrappers and waiting for a capability that was never required. Their models will keep improving, for free, courtesy of someone else’s research budget. Their operating models will not move at all, because no model upgrade re-architects a silo or removes an approval step.
The durable advantage in this cycle is not intelligence. Intelligence is becoming a commodity input with a falling price, available to your competitors on the same terms. The advantage is the set of structural choices that determine how fast your company can convert that cheap input into decisions executed at scale — the pipeline, the interfaces, the experiment rate, and the willingness to take a human off the critical path. Those choices are boring, they are slow, and they are almost impossible to copy once they compound. The future belongs to the teams that stop chasing the demo and start building the runtime.